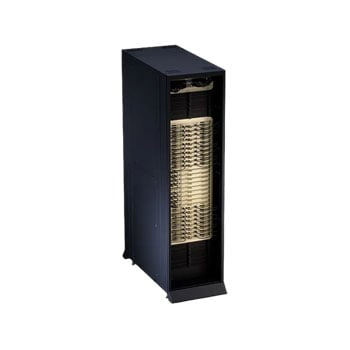
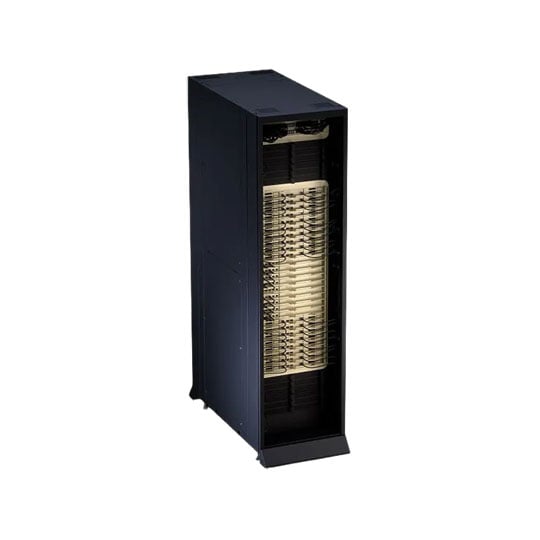
NVIDIA DGX Vera Rubin NVL72 20.7TB HBM4 48U Top Feed AI Supercomputer w/ 3 Year Std. Support
48U NVIDIA DGX Vera Rubin NVL72 AI Supercomputer, 72x NVIDIA Rubin, 20.7TB HBM4, NVIDIA Vera, CX-9, 3yr Std Support
Email me when the availability or price changes
Suggested Alternatives
 2U NVIDIA DGX Rubin NVL8 AI Supercomputer, 8x NVIDIA Rubin, 2.3TB HBM4, 2x Intel Xeon 6776P, CX-9, 3yr Std SupportNVIDIA DGX Rubin NVL8 Intel Xeon 6776P 2.3TB HBM4 2U AI Supercomputer w/ 3 Year Std. Support
LN175221
No customer review
Key Specifications
- 2U NVIDIA DGX Rubin NVL8 AI Supercomputer
- 8x NVIDIA Rubin
- 2.3TB HBM4
- 2x Intel Xeon 6776P
- CX-9
- 3yr Std Support
Call for price

NVIDIA Vera Rubin NVL72 48U AI Supercomputer
with 3 year Standard Support

Powering the Era of AI Agents The 48U NVIDIA Vera Rubin NVL72 Top Feed is a turnkey, rack-scale AI infrastructure solution purpose-built for gigascale AI training and inference. Built on the NVIDIA Vera Rubin platform, it unifies 72 NVIDIA Rubin GPUs and 36 NVIDIA Vera CPUs, supported by up to 54TB of LPDDR5X CPU memory, through sixth-generation NVIDIA NVLink, creating a massive shared-memory fabric for demanding AI workloads. With 20.7TB of HBM4 GPU memory, up to 1,400TB/s of total GPU memory bandwidth and a fully liquid-cooled architecture, the NVL72 is designed to accelerate large-scale AI workloads while addressing the power, security and efficiency requirements of modern data centres.
48U Rack Height
36x NVIDIA Vera CPUs
54TB LPDDR5X CPUs Memory
72x NVIDIA Rubin GPUs
20.7TB HBM4 GPU Memory
NVIDIA Rack Scale Clusters
Turnkey AI Factories NVIDIA rack scale infrastructures are the de facto blueprint for the AI factory. Each rack unit contains 72 NVIDIA GPUs, coupled with 36 CPUs and unified memory combined in a Superchip architecture. These communicate via an advanced chip-to chip (C2C) link within each server node and via NVLink, NVSwitch and ConnectX networking across the rack, providing hugely scalable and groundbreaking compute performance.
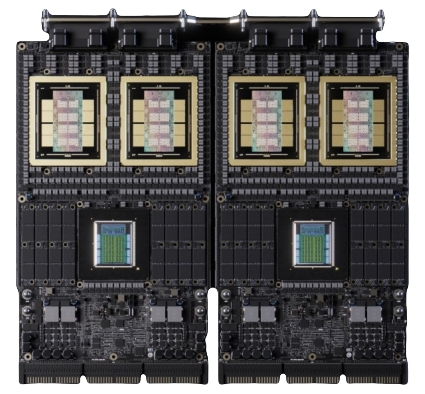
Comprising compute nodes, an AI-ready software stack, management and orchestration tools and enterprise-level support, a Superchip rack scale solution is truly unprecedented.
As an NVIDIA Elite partner and the UK's only DGX Managed Service Provider, Scan can advise on the optimum configuration and install the complete infrastructure.
Driving Down Inference Costs
Revolutionising Throughput
Next-gen Connectivity

Deploying your Rack Scale Cluster Scan is proud to be the UK's only NVIDIA DGX-Ready Managed Services Provider, offering in-country and global customer support. Our managed service portfolio offers a one-stop shop for AI factory customers deploying, managing, and maintaining AI supercomputing infrastructure. Clusters have much more demanding power and cooling requirements than conventional servers. Our technical specialists will perform a site survey to see whether your facilities are suitable or can be adapted. This includes evaluating liquid cooling options, alongside differing power delivery methods, such as integrated PSUs versus busbars. Alternatively, we can arrange installation at one of our NVIDIA-approved hosting partners.
NVIDIA Vera Rubin Superchip

2x NVIDIA Rubin GPUs Per Chip
1x NVIDIA Vera CPU Per Chip
574GB HBM4 GPU Memory Per Chip
Up to 1.5TB LPDDR5X Per Chip
NVIDIA Vera Rubin Platform The NVIDIA Vera Rubin platform is built for the age of agentic AI and reasoning, engineered to master multi-step problem-solving and massive long-context workflows at scale. Vera Rubin is a multi-rack POD-scale system that brings together five purpose-built rack-scale systems into one massive, coherent AI supercomputer. By eliminating critical bottlenecks in communication and memory movement, the platform supercharges inference, delivering more tokens per watt and lower cost per token compared to the NVIDIA Blackwell architecture.

Built for AI Factories NVIDIA Vera is designed for the CPU workloads behind agentic AI and reinforcement learning, including code execution, tool use, sandboxing, analytics, data pipelines and orchestration. Operating as either a host CPU for accelerated systems or a standalone processor, Vera combines energy-efficient NVIDIA Olympus cores with high-bandwidth LPDDR5X memory to keep GPUs fed and AI workloads running efficiently, delivering up to 80% faster sandbox environment performance than traditional CPU infrastructure.

Speed Meets Scale Traditional AI inference architectures often trade off interactivity, intelligence and throughput. NVIDIA Groq 3 LPX addresses these demands as a low-latency inference accelerator for NVIDIA Vera Rubin, designed for agentic AI workloads requiring responsive performance and large context windows. Its co-designed architecture combines the performance of NVIDIA Rubin GPUs and Groq LPUs to deliver interactive, high-throughput inference.
Next-Gen Data Infrastructure NVIDIA STX is a modular foundation for AI-native data platforms, bridging AI compute and storage through intelligent data management. Built on the NVIDIA Vera Rubin platform, BlueField-4 and Spectrum-X networking, STX enables partners to develop a universal data engine that accelerates the AI lifecycle, from training and analytics to real-time agentic inference.

World’s First Ai Ethernet Platform The NVIDIA Spectrum-X Ethernet platform is designed for large-scale AI training and deployment, combining Spectrum-X Ethernet switches and SuperNICs to deliver high-performance AI networking. It connects compute fabrics within data centres, scales across multiple AI data centres with Spectrum-XGS Ethernet, and supports co-packaged optical switching to improve power efficiency and workload resilience.
Frequently Asked Questions (FAQ)
A Superchip server is a SoC (system on chip) architecture where the CPU, GPU and memory are combined on a single chip, rather than separate components.
A cluster is a collection of connected server nodes within a rack environment. It is designed from the ground up as a single architecture, with each server node connected to the next, rather than separate servers simply placed in the same rack.
Whereas several connected servers can deliver enhanced performance by acting as a single coherent unit, a cluster is designed from the ground up to remove as many bottlenecks and latencies as possible, so the resulting unified architecture will outperform the equivalent number of connected servers.
ProArt Laptops are powered by RTX Spark and empower creators to render ultra-large 90GB+ 3D scenes, edit 12K 4:2:2 video, generate 4K AI videos, and run 120B-parameter LLMs with up to 1 million tokens of context using local agents.
Think of an AI factory as a manufacturing plant for intelligence. Raw data goes in. Insights, trained models and real-time predictions come out. Unlike a general-purpose datacentre, it's built to continuously train and deploy AI models, turning data into useful intelligence at scale.
Any organisation that wants to scale AI use efficiently and responsibly can benefit from an AI factory, including:
• Enterprises managing large datasets and multiple AI projects.
• Healthcare providers using AI for diagnostics or patient management.
• Financial institutions deploying AI for fraud detection or risk modelling.
• Retailers and e-commerce companies focused on personalisation and demand forecasting.
• Manufacturers aiming to automate processes or predict maintenance.
• Government and research bodies working with sensitive or high-volume data.
AI factories offer several benefits that help businesses mature their AI use:
• Faster results – automated data prep, training and deployment cut lead times.
• Scalability – reuse pipelines and models across teams and use cases.
• Consistency – standardised workflows reduce errors and technical debt.
• Better ROI – lower operational costs, stronger model performance.
• Governance and compliance – centralised control over data usage, lineage and versioning.
• Adaptability – works with cloud, hybrid or on-premise environments.
Yes. Small businesses can use cloud platforms with pre-built templates and low-code tools, making it easier and more affordable to deploy AI workflows without building complex infrastructure from scratch. Contact our Scan Cloud team for a readiness check.
An AI factory helps your business scale AI by systematising the model development pipeline, allowing teams to reuse components, reduce development time, ensure consistency, and deploy models faster. This scalability is essential for companies looking to integrate AI into multiple departments or products.
Yes, AI factories can integrate across environments. Hybrid and multi-cloud setups allow companies to process data where it lives – whether in the cloud, at the edge (e.g., IoT devices), or in secure on-premises systems – always ensuring flexibility and compliance. Contact our AI team for your readiness check today.
Yes. AI factories can support real-time AI inference and batch processing simultaneously, using intelligent workload management to balance low-latency applications with large-scale AI workloads while maximising GPU utilisation and performance.
Yes, as a leading NVIDIA Elite partner and the UK's only certified NVIDIA DGX Managed Services Provider (MSP), Scan sells all the individual elements to create your own AI factory. This includes NVIDIA DGX and NVIDIA Run:ai software licences. We also offer a range of professional services for ease of deployment and management.
Migrating to an AI factory model is a strategic move that requires planning, the right tools, and experienced support. Scan acts as your specialist partner to streamline this transformation, bringing technical expertise, cutting-edge infrastructure, and industry-proven workflows.
Here's how the migration journey typically unfolds with Scan by your side:
• Discovery & assessment – starting with a full audit across the whole business that identifies bottlenecks in data prep, model development, and deployment.
• AI factory blueprint design – our teams work with you to design a scalable and secure AI factory architecture tailored to your goals, including standardised data ingestion pipelines, reusable model training and deployment workflows, governance and monitoring frameworks, and on-premise, cloud, or hybrid infrastructure integration.
• Infrastructure & platform setup – choose infrastructure and tools that support scalability, are built for performance, security and long-term growth.
• Automation and MLOps integration – we help operationalise your AI workflows with best-in-class MLOps practices, introducing version control, CI/CD pipelines, model monitoring, and retraining strategies to enable continuous delivery of AI models across teams and business units.
• Team enablement – Scan not only builds the factory, we empower your team to run it. Alongside NVIDIA, we can provide documentation, training, and ongoing support to ensure your data scientists, engineers, and decision-makers can maintain, scale, and improve the system confidently.
• Ongoing optimisation & support – your AI factory isn't a static solution. Scan offers long-term support and optimisation services, helping you manage compute resources efficiently, track carbon usage, refine models, and adopt emerging AI tools.