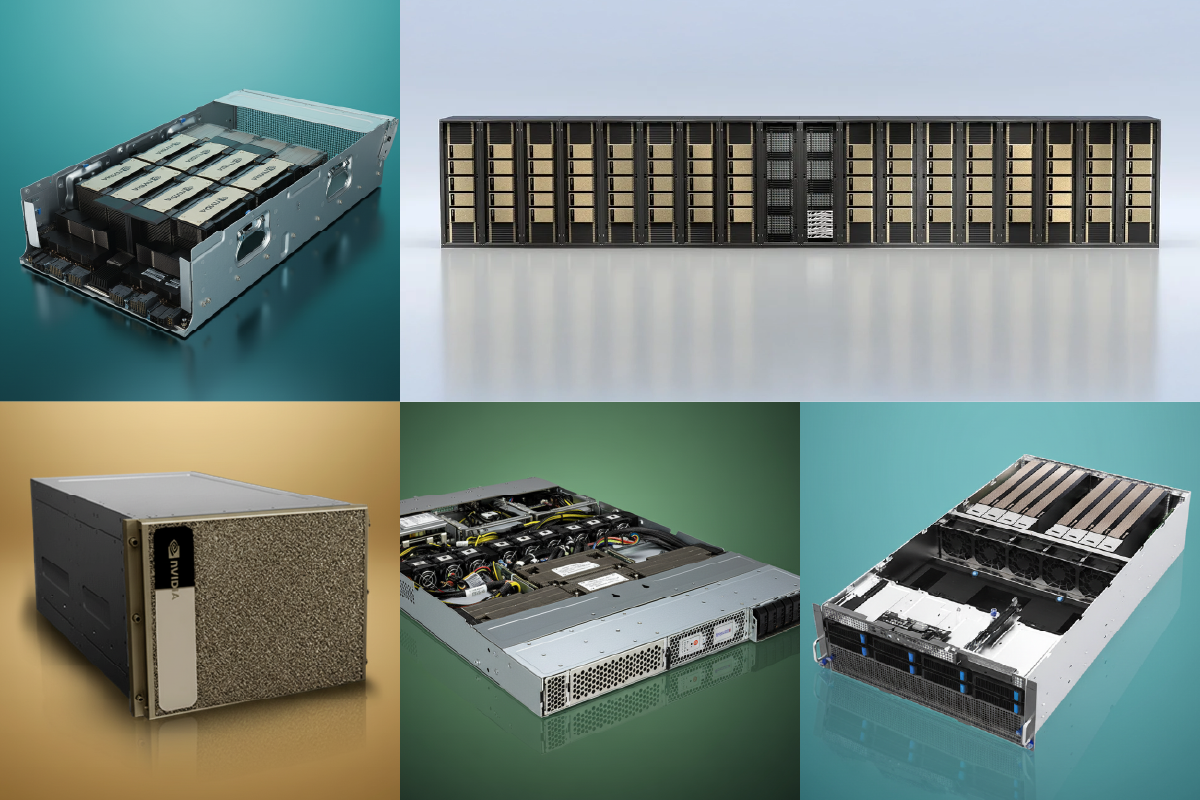
Once a development pipeline has been established, the next steps are to train the AI model, and then inference data using the model. The training phase requires far more GPU and storage resource than during development, as many iterations will be needed. Once a model has been trained, the compute requirement during the inferencing phase is largely determined by how the model will be used in the real world.
For instance, a model that is used to perform quality control checks on a factory assembly line will be small enough to run on embedded devices, often referred to as edge AI. In contrast, an LLM that is used to generate content or perform a customer service role will require the same, if not potentially more compute than during the training phase. This is because the model will be exposed to new data and so will continuously iterate for the length of the project.
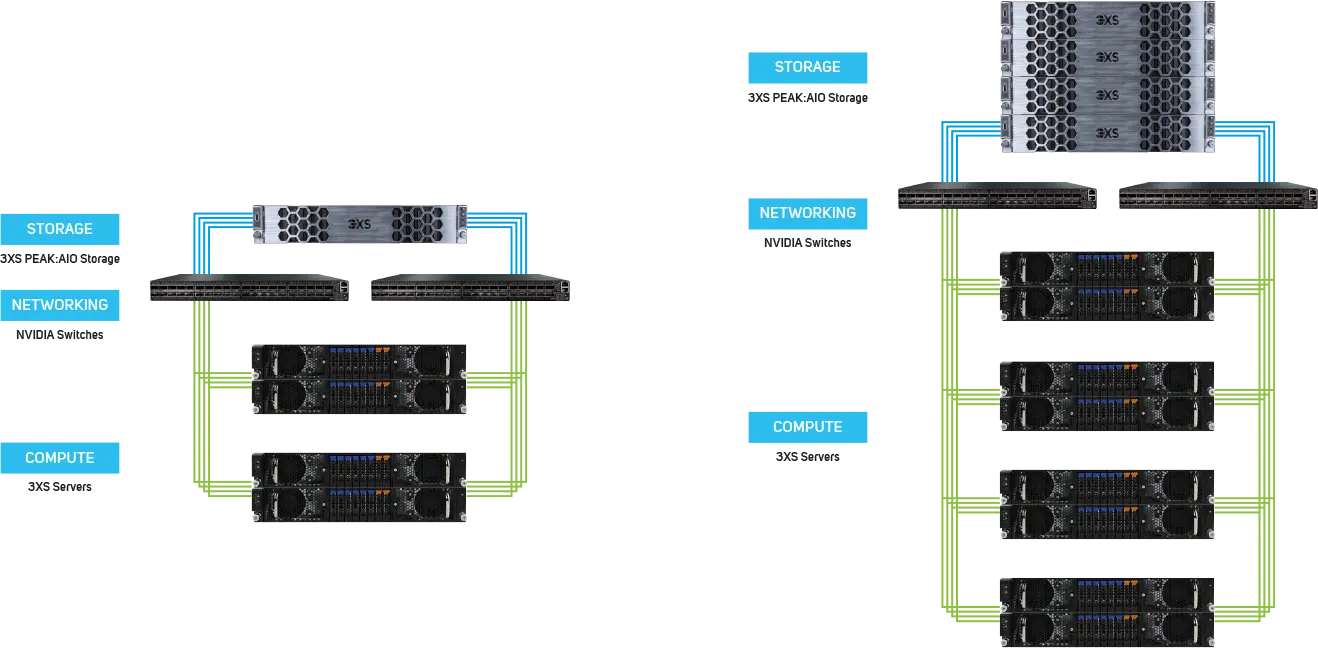
This type of inferencing and training requires at minimum a multi-GPU server, supported by fast storage and connected via high-throughput, low-latency networking. If these three component parts of your AI infrastructure are not matched or optimised, productivity and efficiency will be impacted. The fastest GPU-accelerated supercomputer will be a waste of money if connected to storage that cannot keep its GPUs fully utilised.
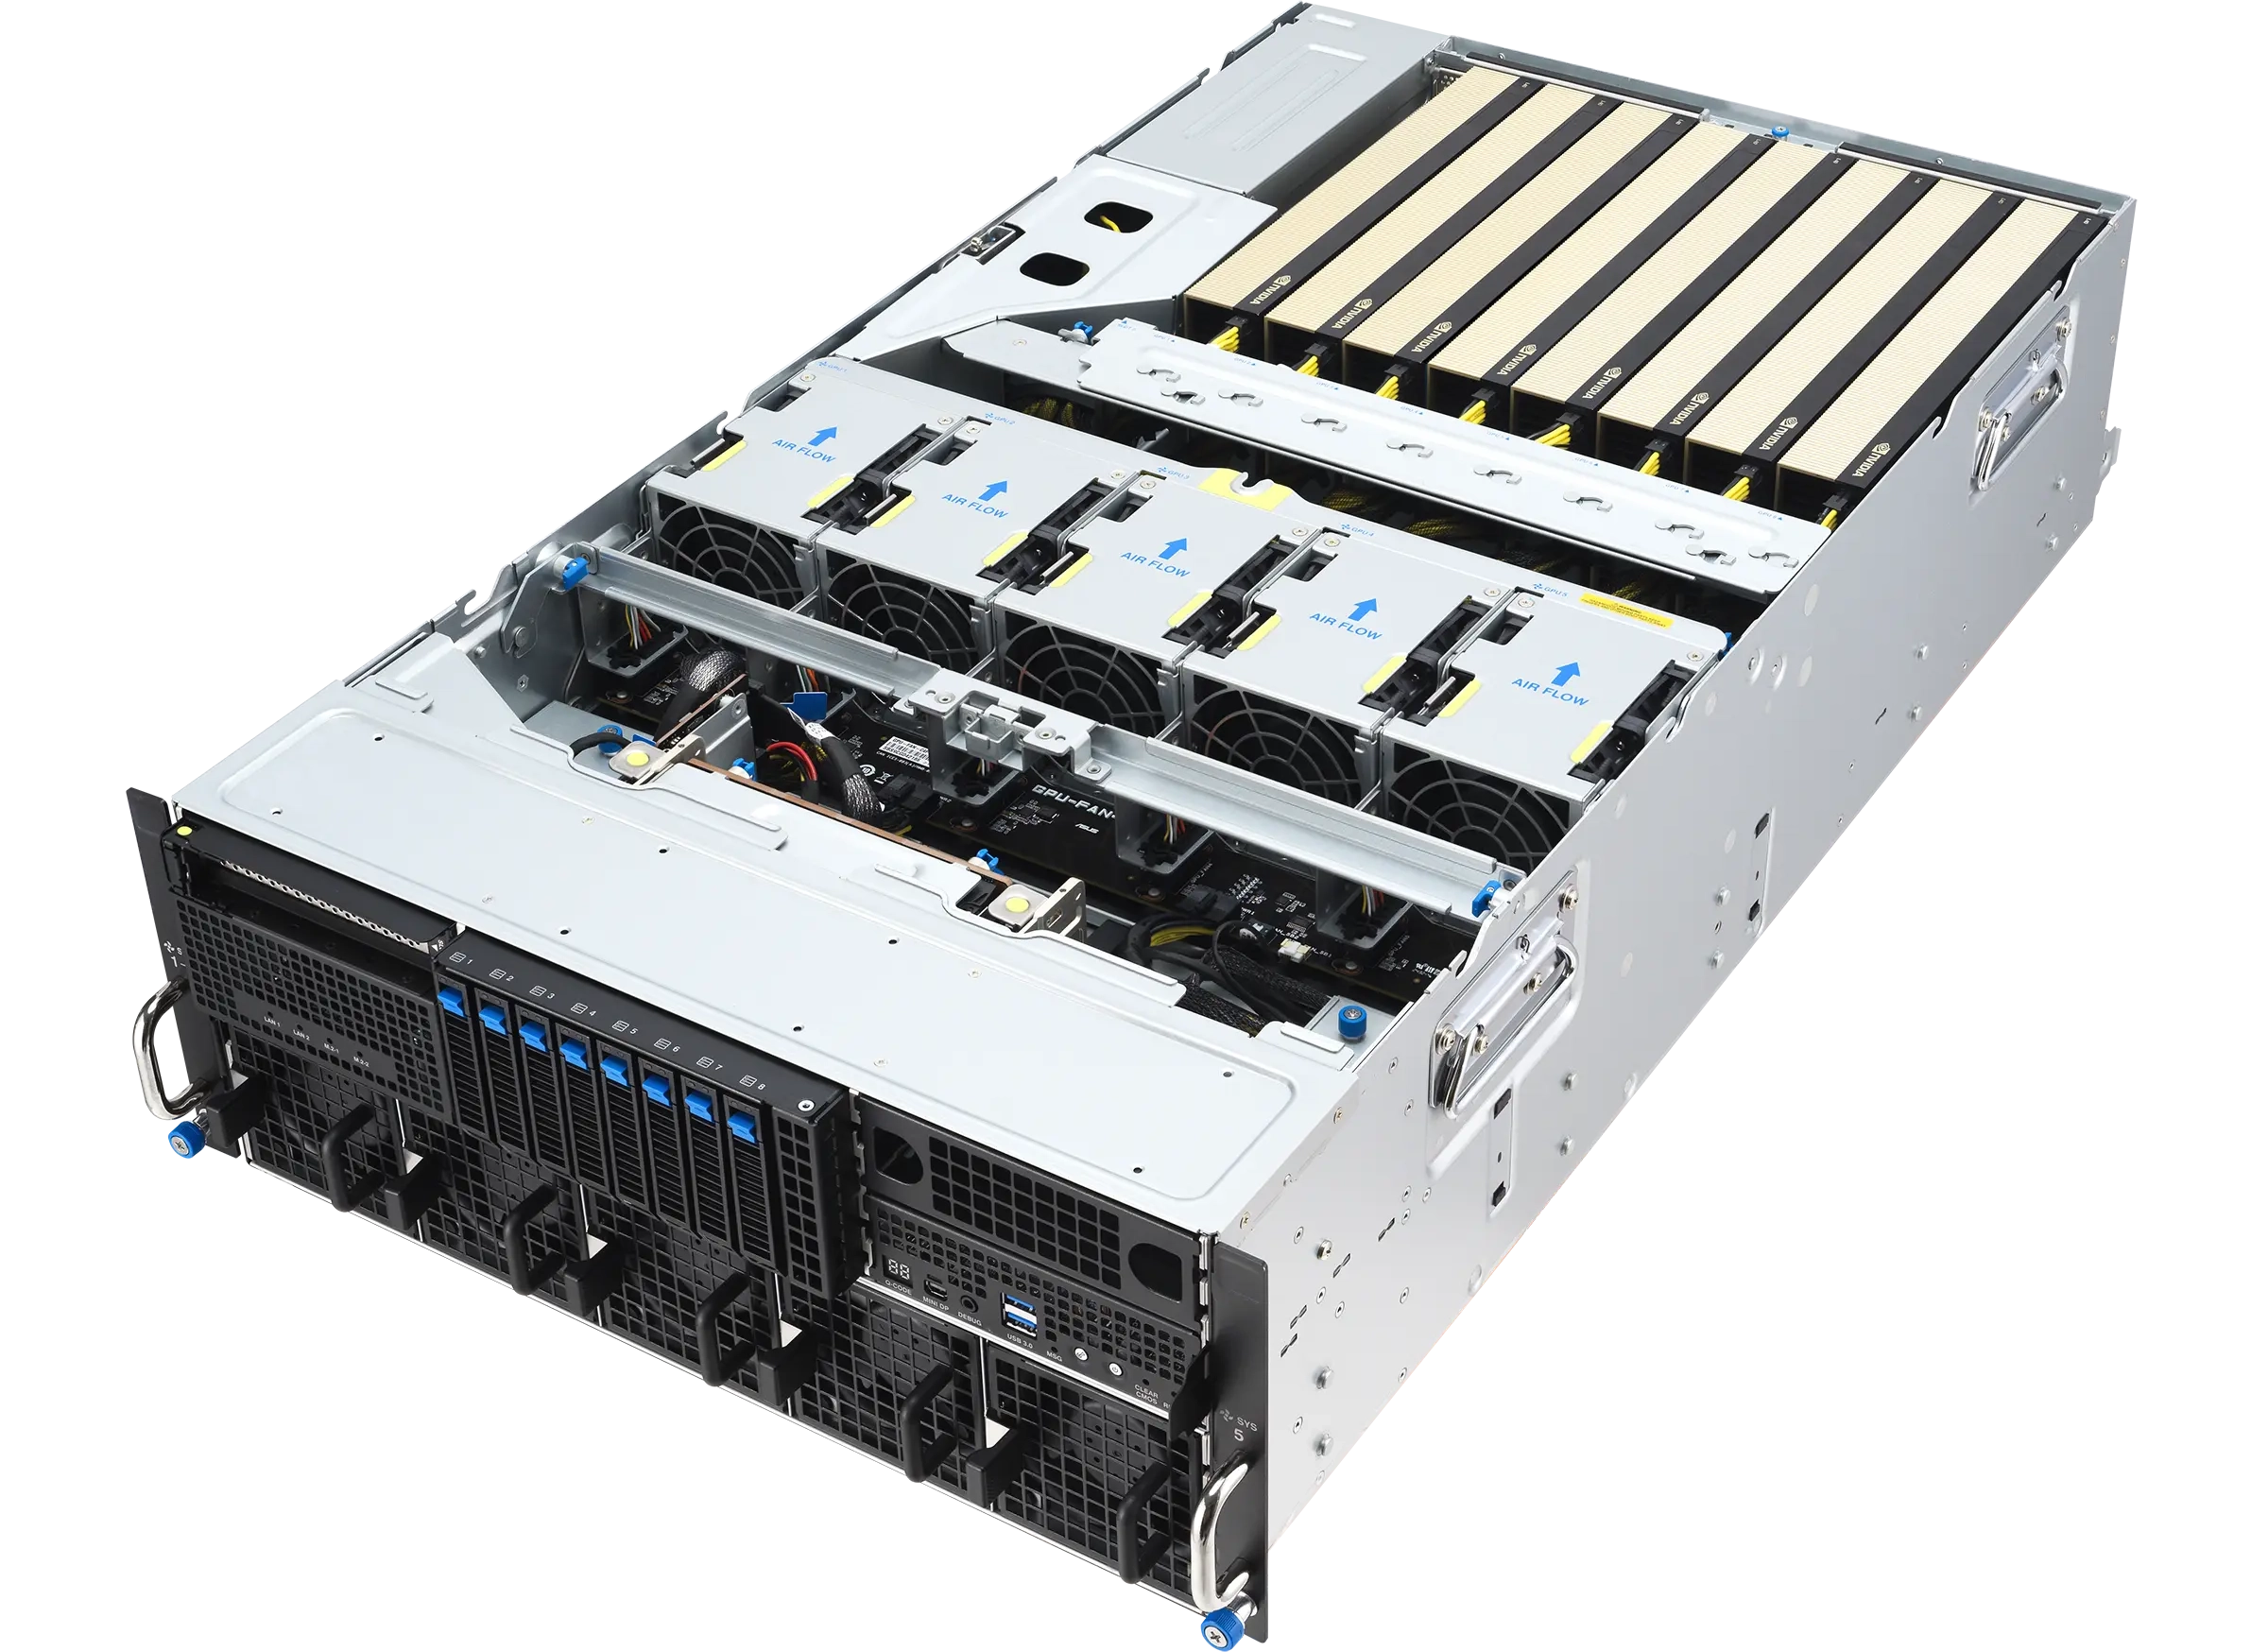
3XS RTX PRO, MGX and EGX
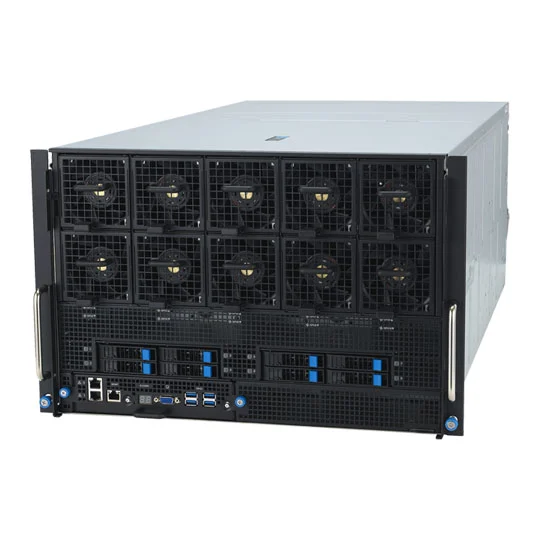
3XS HGX
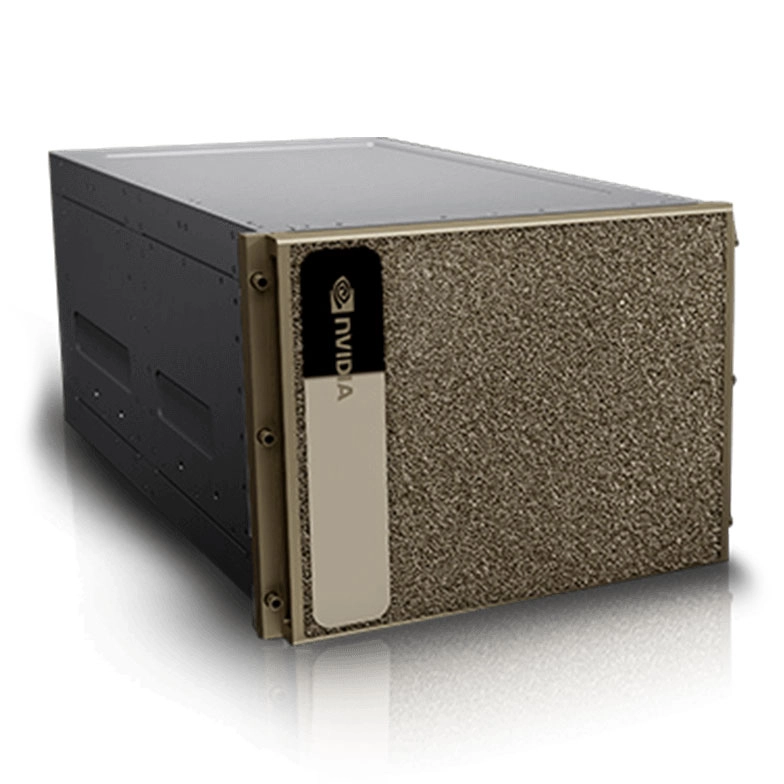
NVIDIA DGX
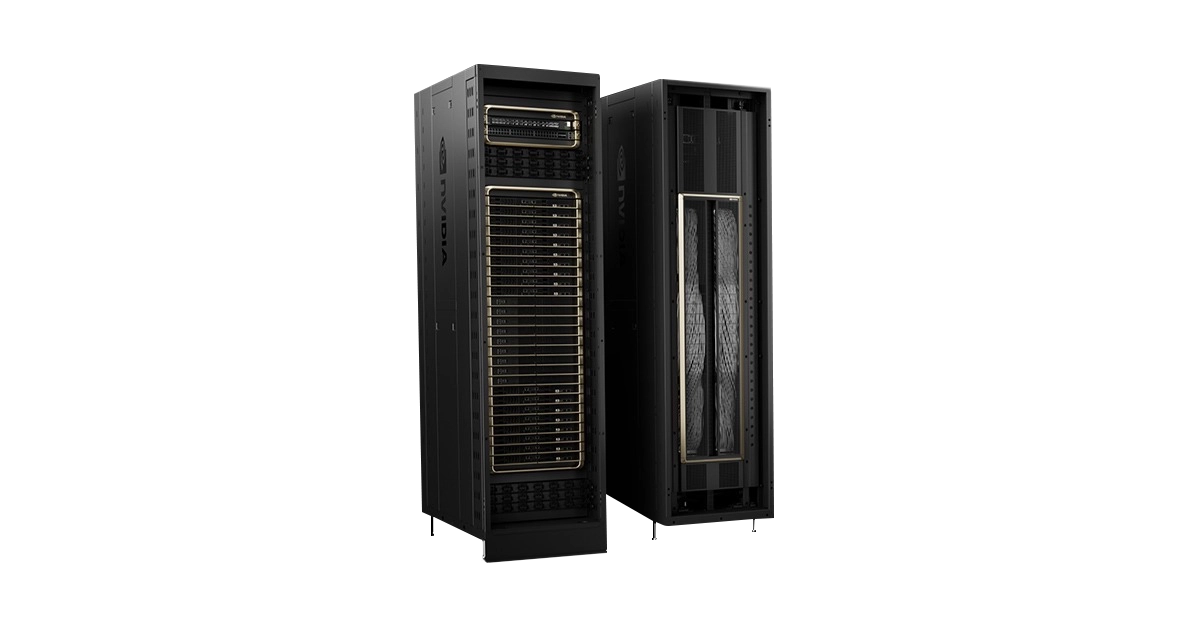
Rack Scale
Your AI Project
The training of an AI model is always preceded by the project scoping, data preparation and AI development phases, and followed by integration and ongoing governance.
target
Problem Statement
Project scope and high-level ROI.
arrow_forward
database
Data Preparation
Classification, cleaning and structure.
arrow_forward
developer_board
Model Development
Education and resource allocation.
arrow_forward
model_training
Model Training
Optimisation, scaling and inferencing.
arrow_forward
hub
Model Integration
Inferencing and deployment.
arrow_forward
policy
Governance
Maintenance and compliance.
Ensuring your project scope is realistic and achievable has a large impact on what AI training and inferencing hardware you will ultimately require. These early stages are crucial to get right. Learn more in our AI Project Planning Guide and AI Development Hardware Buyers Guide.
AI Model Training and Inferencing
Your AI model development phase will likely have involved using frameworks or optimised foundation models to save time and effort when building your AI pipeline, all available in the NVIDIA AI Enterprise software platform. This is optimised for NVIDIA GPUs and included with NVIDIA DGX development platforms and the DGX servers discussed later in this guide. NVIDIA AI Enterprise is also available on subscription for non-DGX servers.
NVIDIA AI Enterprise provides end-to-end implementation of AI projects such as medical imaging, autonomous vehicles, avatars, drug discovery, generative AI, agentic AI, physical AI and robotics, scaling across development, training and inferencing platforms.
The type of AI model and use case has a massive impact on model size when you get to the training and inferencing phases. It is therefore key to understand the relative size of models, how they might scale and the GPU servers that will be required. Between the 1950s and 2018, AI model size grew by seven orders of magnitude, from thousands to 30 million parameters. From 2018 to 2022 alone, it grew another four orders of magnitude, from 30 million to 20 billion parameters. As of 2026, trillion-parameter models are not uncommon.
The table below shows the most popular types of model, including small language models, large language models, vision language models, multimodal AI, agentic AI and physical AI.
AI model use cases, parameter ranges, fine-tuning datasets and recommended servers.
Document AI, visual inspection, OCR, image search, medical imaging
7B-90B
50-500GB
HGX server or DGX appliance
Multimodal AI
Video analytics, speech and vision, digital assistants, autonomous systems
20B+
100GB-2TB
HGX server or DGX appliance(s)
Agentic AI
Customer service, workflow automation, research assistants, software engineering
Multiple foundation models
Variable, typically 100GB-1TB+
NVIDIA DGX Clusters
Physical AI
Robotics, autonomous vehicles, industrial automation, digital twins
200B+
1TB-PB+
NVIDIA DGX Clusters
It is worth clarifying that this table is for guidance only. The absolute size in GB of any model is determined by the number of parameters and the size of each parameter. Similarly, there will be small agentic AI models if their function is very focused and very large LLMs depending on how precise a chatbot needs to be. The dataset size is the likely final size, so you also need capacity for numerous versions and many iterations before reaching the final model.
AI Hardware
The following AI training and inferencing hardware options are compared in light of the model sizes above, with recommendations about the most suitable option for various scenarios. Thorough planning and scoping will provide much more accurate provisional model sizes and better insight into development, training and inferencing hardware choices.
Traditional AI servers use one or more x86 CPUs from AMD or Intel plus multiple NVIDIA GPUs in PCIe or SXM form factors. PCIe is a well-established, cost-effective architecture that is easy to configure and upgrade. SXM modules are not upgradeable, but support more advanced GPUs, larger memory capacities and high-bandwidth GPU interconnects.
NVIDIA rack-scale systems combine Arm-based CPUs and embedded GPUs into densely integrated, liquid-cooled infrastructure. This architecture enables large clusters with coherent memory shared across processors for the most demanding AI workloads.
Choose a hardware family below, or contact our AI team for project-specific advice.
3XS RTX PRO, MGX and EGX Servers
3XS RTX PRO, MGX and EGX servers are based on NVIDIA-certified designs and differ from the other types of AI server in being configurable. This means you get to choose the number and type of GPUs, CPUs, RAM, storage and networking to meet the needs of your project. You could even start with a server with a small number of GPUs and add more later as your budget allows. As the name suggests, RTX PRO servers are available with RTX PRO GPUs, whereas MGX and EGX servers support a wider range of GPUs and networking.
These servers are fine-tuned by our 3XS Systems hardware engineers and workload specialists, and supplied with a custom Linux Ubuntu-based software stack for maximum performance and reliability.
Architecture
These flexible servers support multiple NVIDIA datacentre-grade PCIe form factor GPUs for maximum performance and reliability. A simple comparison is detailed below. For more information, read our NVIDIA Datacentre GPU Buyers Guide.
Specifications per GPU for RTX PRO, EGX and MGX server options.
Specification
RTX PRO 6000 Blackwell Server Edition
RTX PRO 4500 Blackwell Server Edition
H200 NVL
L40S
RTX 6000 Ada
CPUs
2x AMD EPYC / Intel Xeon
2x AMD EPYC / Intel Xeon
2x AMD EPYC / Intel Xeon
2x AMD EPYC / Intel Xeon
2x AMD EPYC / Intel Xeon
GPUs
Up to 10x Blackwell
Up to 10x Blackwell
Up to 8x Hopper
Up to 10x Ada Lovelace
Up to 10x Ada Lovelace
Cooling
Passive
Passive
Passive
Passive
Active
GPU memory
96GB GDDR7
32GB GDDR7
141GB HBM3e
48GB GDDR6
48GB GDDR6
GPU memory bandwidth
1.6TB/s
0.8TB/s
4.8TB/s
0.9TB/s
0.9TB/s
NVLink
✖
✖
4th gen
✖
✖
NVSwitch
✖
✖
✖
✖
✖
NVLink bandwidth
✖
✖
0.9TB/s
✖
✖
MIG instances
4
2
7
✖
✖
FP4 performance
4 PFLOPS
1.6 PFLOPS
3.3 PFLOPS
1.4 PFLOPS
1.4 PFLOPS
Specifications and performance are listed per GPU.
For maximum customisation, these GPUs can be combined with either AMD EPYC or Intel Xeon CPUs. We offer both air and water-cooled servers with up to 10 GPUs, providing extremely high compute performance and a large combined memory pool. Learn more in our AMD EPYC CPU Buyers Guide and Intel Xeon CPU Buyers Guide. Systems support up to 4TB of memory and multiple SSDs. Networking is also configurable with NVIDIA ConnectX SmartNICs, SuperNICs and DPUs; see our NVIDIA Networking Buyers Guide.
The systems are soak tested with deep learning workloads and pre-installed with the latest Ubuntu operating system plus a custom NVIDIA CUDA software stack that includes Docker CE, NVIDIA Container Toolkit and GPU-optimised libraries. An NVIDIA AI Enterprise subscription is required for frameworks and applications.
Scaling Up
Multiple 3XS RTX PRO, EGX and MGX servers can be connected into a POD architecture with shared AI-optimised software-defined storage and NVIDIA Ethernet or InfiniBand networking.
NVIDIA Run:ai enables intelligent GPU resource management so users can access GPU fractions, multiple GPUs or clusters for workloads at every stage of the AI lifecycle. Its scheduler adds high-performance orchestration to containerised AI workloads and helps keep available compute utilised.
As an NVIDIA Elite Partner, our AI team can help design and deploy 3XS servers at scale on-premise or with our datacentre hosting partners.
3XS HGX Servers
Powered by eight NVIDIA SXM GPUs, HGX servers provide data scientists and researchers with a powerful platform for scaling out AI models. Designed for datacentre environments, 3XS HGX Servers are fine-tuned by our hardware engineers and workload specialists, and supplied with a custom Linux Ubuntu-based software stack for maximum performance and reliability.
Architecture
These semi-configurable servers support eight NVIDIA datacentre-grade SXM form factor GPUs for maximum performance and reliability.
Specifications per system for 3XS HGX server options.
Specification
Rubin NVL8
B300
B200
CPUs
2x AMD EPYC / Intel Xeon
2x AMD EPYC / Intel Xeon
2x AMD EPYC / Intel Xeon
GPUs
8x Rubin
8x Blackwell Ultra
8x Blackwell
Cooling
Liquid
Air
Air
GPU memory
2.3TB HBM4
2.1TB HBM3e
1.4TB HBM3e
GPU memory bandwidth
176TB/s
62TB/s
64TB/s
NVLink
6th gen
5th gen
5th gen
NVSwitch
6th gen
5th gen
5th gen
NVLink bandwidth
3.6TB/s
1.8TB/s
1.8TB/s
MIG instances
56
56
56
FP4 performance
400 PFLOPS
144 PFLOPS
144 PFLOPS
Specifications and performance are listed per system.
These GPUs can be combined with either AMD EPYC or Intel Xeon CPUs. We offer air and water-cooled servers depending on your GPU choice. Learn more in our AMD EPYC CPU Buyers Guide and Intel Xeon CPU Buyers Guide. Systems support up to 4TB of memory and multiple SSDs. Networking is configurable with NVIDIA ConnectX SmartNICs, SuperNICs and DPUs; see our NVIDIA Networking Buyers Guide.
The systems are soak tested with deep learning workloads and pre-installed with the latest Ubuntu operating system plus a custom NVIDIA CUDA software stack. An NVIDIA AI Enterprise subscription is required for frameworks and applications.
Scaling Up
Multiple 3XS HGX servers can be connected into a POD architecture with shared AI-optimised software-defined storage and NVIDIA Ethernet or InfiniBand networking.
NVIDIA Run:ai enables intelligent resource management across GPU fractions, multiple GPUs and clusters. This helps ensure available compute is utilised and adds high-performance orchestration to containerised AI workloads.
As an NVIDIA Elite Partner, our AI team can help design and deploy 3XS HGX servers at scale on-premise or with our datacentre hosting partners.
NVIDIA DGX Appliances
Powered by eight NVIDIA GPUs, NVIDIA DGX appliances provide data scientists and researchers with the most powerful platform for scaling out AI models. Designed for datacentre environments, the NVIDIA DGX range is the ultimate in AI-optimised appliances. Supplied with a complete software stack and management interface, they are supported directly by NVIDIA for maximum uptime and reliability.
Architecture
These appliances support eight NVIDIA datacentre-grade SXM form factor GPUs for maximum performance and reliability.
Specifications per system for NVIDIA DGX appliance options.
Specification
Rubin NVL8
B300
B200
CPUs
2x Intel Xeon
2x Intel Xeon
2x Intel Xeon
GPUs
8x Rubin
8x Blackwell Ultra
8x Blackwell
Cooling
Liquid
Air
Air
GPU memory
2.3TB HBM4
2.1TB HBM3e
1.4TB HBM3e
GPU memory bandwidth
176TB/s
62TB/s
64TB/s
NVLink
6th gen
5th gen
5th gen
NVSwitch
6th gen
5th gen
5th gen
NVLink bandwidth
3.6TB/s
1.8TB/s
1.8TB/s
MIG instances
56
56
56
FP4 performance
400 PFLOPS
144 PFLOPS
144 PFLOPS
Specifications and performance are listed per system.
Unlike the other types of server covered in this guide, the only configurable option on DGX appliances is system memory. They have a predefined configuration of CPUs, networking and storage.
The systems are soak tested with deep learning workloads and pre-installed with the latest DGX operating system, NVIDIA Mission Control management layer and an NVIDIA AI Enterprise subscription including frameworks and applications.
Scaling Up
Multiple NVIDIA DGX appliances can be connected into powerful BasePOD or SuperPOD architectures.
DGX systems are managed by NVIDIA Mission Control, while large fabrics use NVIDIA Unified Fabric Manager. This combines real-time network telemetry with analytics to simplify management of scale-out InfiniBand clusters.
As an NVIDIA Elite Partner and NVIDIA-certified DGX Managed Services Provider, our AI team can help design and deploy DGX solutions at scale on-premise or with our datacentre hosting partners.
NVIDIA Rack Scale Clusters
NVIDIA rack-scale clusters are designed to handle terabyte-class models for massive recommender systems, agentic and physical AI, and AI factory deployments. These clusters comprise multiple compute units and networking, and require facility-level liquid cooling.
Architecture
These cluster systems are designed for scale-out, starting with a single rack comprising dozens of custom-built NVIDIA GPUs and NVIDIA CPUs for maximum performance and reliability.
Specifications per system for NVIDIA rack-scale cluster options.
Specification
Vera Rubin NVL72
GB300 NVL72
GB200 NVL72
Host CPUs
36x NVIDIA Vera
36x NVIDIA Grace
36x NVIDIA Grace
GPU architecture
72x Rubin
72x Blackwell Ultra
72x Blackwell
Cooling
Liquid
Liquid
Liquid
GPU memory
20.7TB HBM4
20TB HBM3e
13.4TB HBM3e
GPU memory bandwidth
1,580TB/s
576TB/s
576TB/s
NVLink
6th gen
5th gen
5th gen
NVSwitch
6th gen
5th gen
5th gen
NVLink bandwidth
7.2TB/s
3.6TB/s
3.6TB/s
MIG instances
576
576
576
FP4 performance
3,600 PFLOPS
1,440 PFLOPS
1,440 PFLOPS
Specifications and performance are listed per system.
Like DGX appliances, rack-scale clusters are not configurable. They have a predefined configuration of CPUs, memory, networking, storage and software.
The systems are soak tested with deep learning workloads and pre-installed with the latest DGX operating system, NVIDIA Mission Control management layer and an NVIDIA AI Enterprise subscription including frameworks and applications.
Scaling Up
A rack-scale cluster already operates at considerable scale, but the architecture is intended for multi-rack configurations. These systems connect hundreds of fully linked GPUs and deliver exascale AI performance.
As an NVIDIA Elite Partner and NVIDIA-certified DGX Managed Services Provider, our AI team can help design and deploy rack-scale solutions on-premise or with our datacentre hosting partners.
Comparative Performance
When choosing an AI training and inferencing platform, it is important to consider both raw compute performance, typically measured in FLOPS, and memory capacity, which determines how large an AI model can be. This is a fundamental shift from a few years ago, when raw compute performance was the most important factor, and is due to the increasing use of LLMs. The table below compares popular configurations.
Comparative performance, memory, model capacity and cost for AI training and inferencing systems.
System
3XS RTX PRO / EGX / MGX Server
3XS HGX Server / NVIDIA DGX Appliance
NVIDIA Rack Scale Clusters
RTX PRO 6000
RTX PRO 4500
H200 NVL
L40S / RTX 6000 Ada
Rubin NVL8
B300
B200
Vera Rubin NVL72
DGX GB300 NVL72
DGX GB200 NVL72
Analysis
3XS RTX PRO, EGX and MGX give you the flexibility to match the specification to your project, including up to ten GPUs with air and liquid cooling options. PCIe GPU performance and memory are limited compared with SXM systems.
3XS HGX servers and NVIDIA DGX appliances use powerful SXM GPUs for the highest performance and memory in a single system. HGX systems are customisable, while only memory can be changed in DGX appliances.
NVIDIA rack-scale clusters provide an order of magnitude more performance and memory than multiple systems and are purpose-built for the largest parameter AI models.
CPU(s)
2x AMD EPYC / Intel Xeon
2x Intel Xeon
36x NVIDIA Vera
36x NVIDIA Grace
36x NVIDIA Grace
GPU(s)
10x RTX PRO 6000 Blackwell Server Edition
10x RTX PRO 4500 Blackwell Server Edition
8x H200 NVL
8x L40S / RTX 6000 Ada
8x Rubin NVL8
8x B300
8x B200
72x Rubin
72x B300
32x B200
Cooling
Air / Liquid
Air
Air
Air
Liquid
Air
Air
Liquid
Liquid
Liquid
AI performance (FP4 PFLOPS)*
32
12.8
26.4
11.2
400
144
144
3,600
1,440
1,440
GPU memory*
768GB
256GB
1.1TB
384GB
2.3TB
2.1TB
1.4TB
20.7TB
20TB
13.4TB
Trillions of AI model parameters (FP4)*
1.2
0.4
1.7
0.6
3.6
3.3
2.2
32
31.2
20.9
Cost
< LOWERHIGHER >
* Combined figure for all GPUs.
Total Cost of Ownership
This guide focuses on the compute nodes and GPUs that play a critical role in how fast an AI model can be trained and inference data. However, this is only part of the total cost of ownership equation. None of these systems, regardless of performance level, can operate in isolation. They all require AI-optimised storage and specialist networking, especially when scaling out across a cluster. Depending on the number of compute nodes, this can add hundreds of thousands, if not millions, of pounds to the project cost.
Although these systems fit inside industry-standard 19in equipment racks, they have an order of magnitude higher power consumption and cooling requirement than conventional servers. A typical server has a peak power draw of less than 1kW, often much less under everyday load, whereas a single DGX can continuously consume 24kW. This means your datacentre requires specialist power delivery and cooling facilities, particularly for liquid-cooled servers. If your facilities are not suitable, we can perform the installation at one of our NVIDIA-approved hosting partners.
As an NVIDIA Elite Partner and NVIDIA DGX Managed Service Provider, Scan can advise and guide on these requirements through our professional services team.
Proof of Concept
Any of these solutions can be trialled free of charge in our proof-of-concept hosted environment. Your trial will involve secure access where you can use a sample of your own data for realistic insights, guided by our expert data scientists to ensure you get the most from your PoC.
All the AI training servers and appliances covered in this guide can also be provisioned on our Scan Cloud platform. Cloud server solutions can be configured with a wide variety of NVIDIA GPUs or an entire DGX appliance.
payments
Simple, Flexible Pricing
No long-term commitments or hidden storage and networking charges.
speed
GPU Performance
From single GPUs to high-performance eight-GPU systems and clusters.
lan
Performance Infrastructure
NVMe storage and uncontended network ports protect performance and privacy.
tune
Build It Your Way
Custom UK-based IaaS solutions support flexibility and data sovereignty.
Click the links below for further information on specific AI compute nodes. If you still have questions on how to select the perfect system, contact one of our advisors on 01204 474210 or at [email protected].
AI compute nodes can be trialled free of charge in our proof-of-concept hosted environment. Use a sample of your own data for realistic insights with guidance from our expert data scientists.
Scan is an authorised NVIDIA Elite Partner and has helped customers in higher education, healthcare, pharmaceutical, finance and robotics deploy AI projects since 2016.
An AI server differs from a standard server, having hardware and software that has been optimised for training and inferencing AI models. Typically, an AI server has one or two CPUs plus multiple NVIDIA GPUs, with a large amount of system and GPU memory, in order to load AI models with large parameters. Most AI servers run a Linux-derived operating system.
The best AI servers are from the NVIDIA DGX family, available to buy from Scan, as this combines the highest performance GPUs and networking, plus a custom software stack and dedicated enterprise support.
There are also special rack scale clusters, comprising multiple servers, for terabyte-class models for massive recommender systems, agentic and physical AI, and for AI factory deployments.
Scan 3XS Systems has been hand crafting PCs, workstations and servers for more than 30 years. We pioneered the AI dev box back in 2016, so we have a huge amount of experience in building highly reliable deep learning AI servers that deliver the most performance for your budget. Scan is also an authorised NVIDIA Elite Partner and the UK’s only DGX Managed Service Provider.