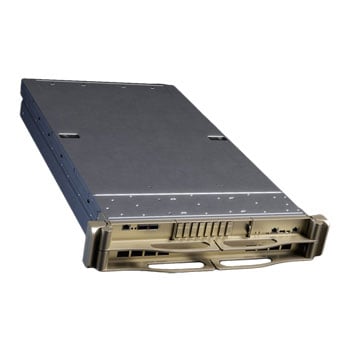
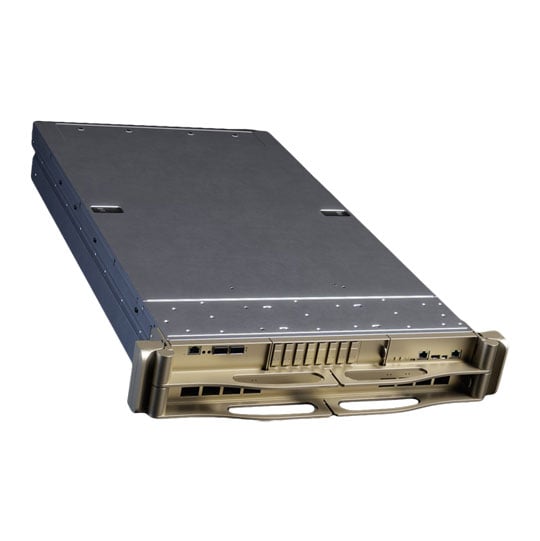
NVIDIA DGX Rubin NVL8 Intel Xeon 6776P 2.3TB HBM4 2U AI Supercomputer w/ 3 Year Std. Support
2U NVIDIA DGX Rubin NVL8 AI Supercomputer, 8x NVIDIA Rubin, 2.3TB HBM4, 2x Intel Xeon 6776P, CX-9, 3yr Std Support
Email me when the availability or price changes
- 48HR REPLACEMENT If you need to return this item, your replacement will be dispatched within 2 working days of your product arriving back at Scan.
Suggested Alternatives
 NVIDIA DGX B300 Deep Learning AI System, 8x B300 GPUs, 2100GB HBM3e, 72 petaFLOPS FP8 Performance, 3yr Std SupportNVIDIA DGX 8x B300 2,100GB AI Server System
LN165851
No customer review
Key Specifications
- NVIDIA DGX B300 Deep Learning AI System
- 8x B300 GPUs
- 2100GB HBM3e
- 72 petaFLOPS FP8 Performance
- 3yr Std Support
£617,999.00Pre order

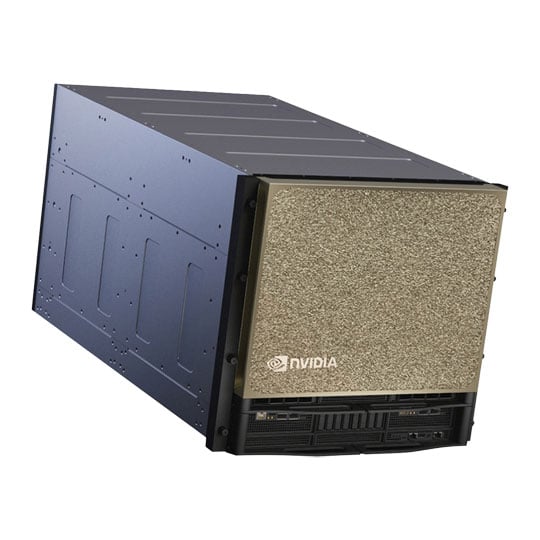
NVIDIA DGX Rubin NVL8 2U AI Supercomputer
with 3 year Standard Support

The Foundation for Intelligence at Scale The NVIDIA DGX Rubin NVL8 is a turnkey AI infrastructure platform built on the NVIDIA Rubin architecture, designed to accelerate demanding agentic AI, physical AI, large-scale Mixture-of-Experts models and massive-context inference workloads. Powered by eight NVIDIA Rubin GPUs with 2.3TB of HBM4 memory and up to 400 PFLOPS of NVFP4 inference performance, the DGX Rubin NVL8 provides the high-performance compute, memory bandwidth and GPU interconnect required for AI workloads at enterprise scale. Two Intel Xeon 6776P processors provide host processing, while fourth-generation HBM4 memory across the eight GPUs delivers 176TB/s of memory bandwidth. Sixth-generation NVIDIA NVLink provides 28.8TB/s of total GPU-to-GPU bandwidth, with eight NVIDIA ConnectX-9 VPI networking interfaces supporting up to 800Gb/s InfiniBand and Ethernet. The system also incorporates NVIDIA BlueField-4 DPUs and NVIDIA Mission Control for integrated infrastructure and workload management.
2U Rack Height
2x Intel Xeon 677P CPUs
8x NVIDIA Rubin GPUs
2.3TB HBM4 GPU Memory
NVIDIA Rack Scale Clusters
Turnkey AI Appliances NVIDIA DGX appliances are the de facto standard for enterprise AI. Powered by eight NVIDIA SXM GPUs communicating via NVLink and NVSwitch, they provide the ultimate in compute performance and memory capacity for agentic AI, reasoning models and physical AI.
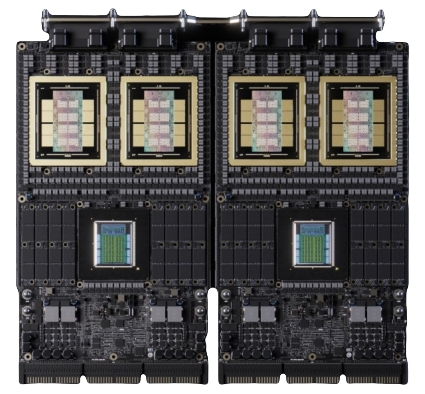
NVIDIA DGX is a whole lot more than a server, it's a turnkey solution, comprising compute node, AI-ready software stack and enterprise-level support.
As an NVIDIA Elite partner and the UK's only DGX Managed Service Provider, Scan can advise on the optimum configuration and install your DGX.
Driving Down Inference Costs
Revolutionising Throughput
Next-gen Connectivity

Deploying your Rack Scale Cluster Scan is proud to be the UK's only NVIDIA DGX-Ready Managed Services Provider, offering in-country and global customer support. Our managed service portfolio offers a one-stop shop for AI factory customers deploying, managing, and maintaining AI supercomputing infrastructure. Clusters have much more demanding power and cooling requirements than conventional servers. Our technical specialists will perform a site survey to see whether your facilities are suitable or can be adapted. This includes evaluating liquid cooling options, alongside differing power delivery methods, such as integrated PSUs versus busbars. Alternatively, we can arrange installation at one of our NVIDIA-approved hosting partners.
Powering the Agentic AI Era

8x NVIDIA Rubin GPUs Per Appliance
2x Intel Xeon CPUs Per Appliance
287.5GB HBM4 Memory Per GPU
2.3TB Total GPU Memory
Powered by NVIDIA Rubin & Intel Powered by eight NVIDIA Rubin GPUs, two Intel® Xeon® CPUs, and sixth-generation NVIDIA NVLink, DGX Rubin NVL8 delivers 400 PFLOPS of NVFP4 inference performance and 280 PFLOPS of NVFP4 training performance. DGX Rubin NVL8 is designed for the world’s most complex AI workloads, from large-scale model training to long-context reasoning and agentic inference. Equipped with 2.3 TB of total GPU memory and 176 TB/s of HBM bandwidth, data moves through the training and inference pipeline as quickly as possible. Sixth-generation NVIDIA NVLink provides 28.8 TB/s of total bandwidth per system, enabling seamless peer-to-peer communication for massive model parallelism. With NVIDIA DGX SuperPOD, enterprises can scale from a single DGX Rubin NVL8 system to an AI factory blueprint without creating new communication bottlenecks.

Built for Agentic AIRubin features a specialised multi-agent engine for reasoning workflows, and a dedicated reinforcement learning engine that optimises memory movement in hardware.

Massive Memory BandwidthThe DGX Rubin NVL8's eight GPUs are supported by 2.3TB of HBM4 memory with 176TB/s of bandwidth, a 1.8x increase over previous generation Blackwell systems.

NVIDIA NVLinkSixth-generation NVLink provides 28.8TB/s of bandwidth between GPUs, double that of fifth-gen NVLink in previous generation Blackwell systems.
Frequently Asked Questions (FAQ)
The NVIDIA DGX Rubin NVL8 is a powerful AI supercomputer designed for agentic and physical AI at scale. It features eight NVIDIA Rubin GPUs, 2.3TB of HBM4 system memory, and 800GB/s high-speed networking. It includes the full NVIDIA AI software stack (additional charge may apply) and is the building block for the upcoming Vera Rubin NVL72 SuperPOD solutions.
The next-generation Rubin platform includes the Rubin GPU (HBM4 memory), NVLink 6 Switch, ConnectX-9 SuperNIC, BlueField-4 DPU, and Spectrum-6 Ethernet / Quantum X800 InfiniBand switch. In contrast the current generation Blackwell includes the Blackwell and Blackwell Ultra GPUs (HBM3e memory), NVLink 5 Switch, ConnectX-8 SuperNIC, BlueField-3 DPU, and Spectrum-4 Ethernet / Quantum-2 InfiniBand switch.
Every aspect of the latest Rubin platform features an uplift in performance over the previous generation, resulting in significantly higher performance than Blackwell-based ones.
The DGX Rubin NVL8 is optimised for demanding AI workloads such as Agentic AI, Physical AI, large-scale Mixture-of-Experts (MoE) Models, Massive-Context Inference and next-generation AI factories.
Yes. Scan is an official UK NVIDIA Elite Partner and will be offering the DGX Rubin NVL8 with full configuration, deployment, and support services. Scan is the only UK-based DGX Managed Services Provider (MSP) that enables businesses to access the power of DGX infrastructure without needing the skillset on-site to oversee the infrastructure. Instead, DGX MSPs provide full wraparound services to assist with anything from the initial deployment & configuration through to on-going services that encompass support, updates and overall platform management.